

Headroom: local, recoverable context compression for agents
headroomlabs-ai/headroom · 73,787★ · 5,692 forks
Everything worth knowing about chopratejas/headroom: a local layer that shrinks the context models receive, with a library, proxy, MCP server, and agent adapters.
What Headroom is
Headroom is a context-optimization tool for AI applications and agents. It compresses tool outputs, logs, files, retrieval-augmented generation (RAG) snippets, and history before they reach the model. The stated goal is to preserve the response while cutting input tokens: the README claims 60% to 95% for JSON data and 15% to 20% for coding agents.
The repository’s tail identity, chopratejas/headroom, currently redirects to headroomlabs-ai/headroom. The historical name is kept in the record; the links, status, and metrics in this report correspond to the canonical repository. It is not a model or a provider: it can be used as a Python or TypeScript library, a local proxy, an agent wrapper, or an MCP server.
The origin: a response to growing tool-call context
GitHub’s API dates the repository’s creation to January 7, 2026. Its top contributor is Tejas Chopra (chopratejas), listed with 1,089 contributions; his GitHub profile identifies him as Tejas Chopra, lists Netflix, Inc. as his company, and Los Gatos as his location. That attribution does not demonstrate that Netflix sponsors Headroom.
In the Hacker News thread 46602761, Chopra explained the trigger from his own experience: running agents with tool calls could cost him $200 a day because search results, database queries, and listings repeatedly bloated the context. His approach was not simply trimming text: keep the original locally so the model can retrieve it if the compressed version falls short.
The same comment described a tension with widening the context window and with truncation: a bigger window only postpones the cost, while truncation or a summary can strip out information a tool call with a strict contract needs. That account is the author’s stated motivation, not an independent measurement of cost or accuracy.
Philosophy and principles
Current documentation surfaces four operating principles:
- Content-aware compression:
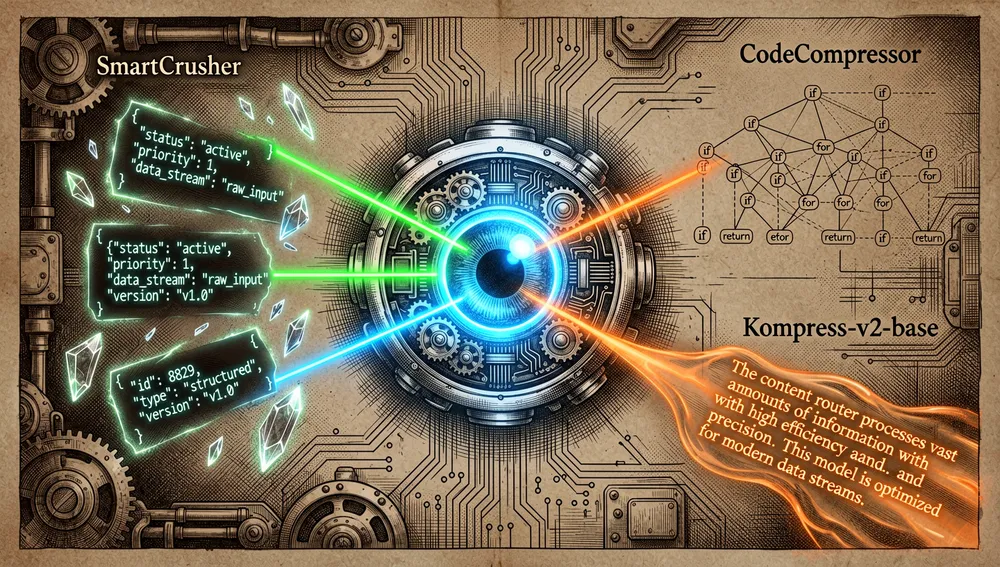
ContentRouterdetects the type and picks between SmartCrusher for JSON, a syntax-tree-based CodeCompressor, and the Kompress-v2-base model for prose. - Recoverability before permanent deletion: reversible CCR compression keeps originals in a local cache and exposes
headroom_retrievewhen the model needs the full content. - Local execution and safe failure: the README states that data stays local, and that if JSON parsing or compression fails, the content is forwarded unmodified.
- Explicit measurement of limits: the project distinguishes estimated output savings from measured ones and offers a control group via
HEADROOM_OUTPUT_HOLDOUT.
The “same answer” promise depends on the scenario and the configuration. The documentation itself acknowledges that the relevance score is heuristic, can drop an important outlier element, and is not appropriate when an application requires every row of a result.
How it works
Headroom offers four main paths:
| Mode | Documented pattern | Concrete use |
|---|---|---|
| Library | from headroom import compress or the TypeScript SDK | Compress messages inside an application. |
| Proxy | headroom proxy --port 8787 | Insert a local layer without changing client code. |
| Agent wrapper | headroom wrap claude and headroom unwrap <tool> | Launch an agent with the proxy and configuration already set up. |
| MCP | headroom mcp install or headroom mcp serve | Expose compression, retrieval, and stats to an MCP client. |
Documented installation uses uv tool install --python 3.13 "headroom-ai[all]" for the command-line interface, pip install "headroom-ai[all]" for Python, and npm install headroom-ai for the TypeScript SDK. The npm package does not include the headroom executable.
Once installed, headroom doctor checks routing, headroom perf shows results, and headroom dashboard presents savings while the proxy is running. headroom deploy prepares a local deployment.
wrap mode is documented for Claude Code, Codex, Grok CLI, Aider, Copilot CLI, OpenCode, Cline, Continue, Goose, OpenHands, Mistral Vibe, Oh My Pi, Kimi CLI, and ZCode; Cursor requires manual proxy configuration. The README also lists library integration with LangChain, Agno, Strands, AnyLLM, and Bedrock.
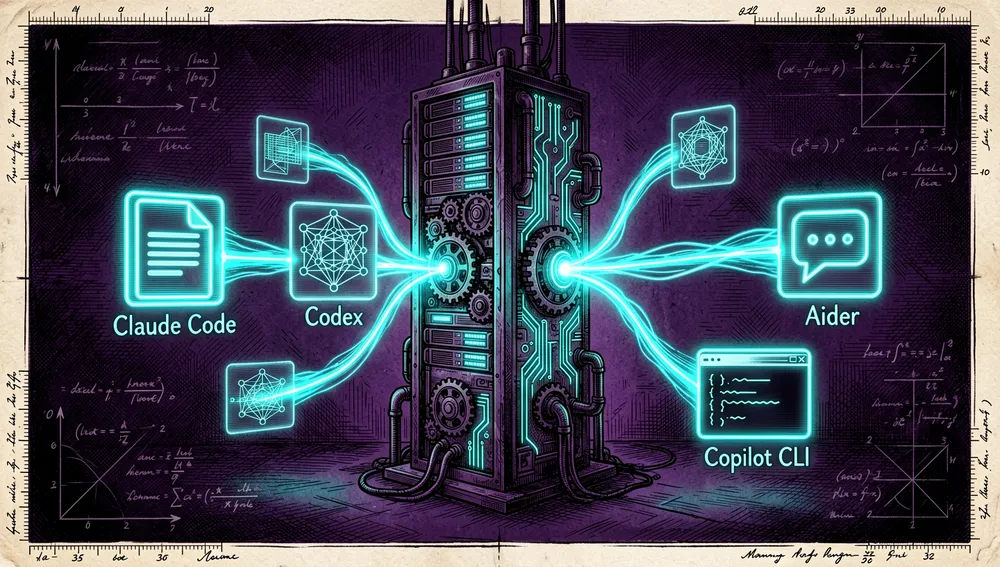
The documented architecture routes content to a specialized compressor. CCR keeps the original and allows a full version to be retrieved; CacheAligner only detects volatile content that could invalidate a provider’s cache prefixes and does not rewrite messages. In addition, headroom learn analyzes failed sessions and writes corrections into instruction files such as CLAUDE.local.md, AGENTS.md, or GEMINI.md.
Official and semi-official status
No evidence was recovered that Headroom has been accepted into an official marketplace run by Anthropic, OpenAI, Cursor, or another provider, nor of a formal certification or endorsement from those providers. The README’s matrix declares technical compatibility with Anthropic, OpenAI, and other clients and APIs, but compatibility is not the same as endorsement or official distribution.
There is a limited, semi-official form of adoption: the project itself maintains the adapters, the headroom-ai PyPI package, the ghcr.io/chopratejas/headroom:latest image, and the headroomlabs-ai organization. With 64,238 stars and 4,883 forks at the time of measurement, it is visible as an open-source project, but the sources recovered do not justify calling it a de facto standard.
The ecosystem
Organization repositories
Querying GitHub’s API for headroomlabs-ai found these public companions:
headroomlabs-ai/tokview: a local proxy and dashboard that attributes tokens and cost to tool calls across Claude, OpenAI, and Gemini; 66 stars and 9 forks.headroomlabs-ai/strands-headroom: a context-compression integration for AWS Strands agents; 0 stars and 0 forks at the time of measurement.
The README also recommends Serena for semantic code navigation and mentions Ponytail, Graphify, Caveman, and memory MCP servers as tools that can sit ahead of Headroom in a pipeline. That mention establishes conceptual compatibility, not an affiliation, dependency, or certified integration with those projects.
Forks, translations, and community extensions
The forks API sorted by stars provides concrete evidence of derivatives, though a fork does not imply support from the upstream project:
Hust-wahaha/headroom-zh: a Chinese-language fork focused on Chinese agent workflows and context fidelity; 147 stars and 5 forks.vmamuaya/headroom-ollama: a fork that adds Ollama to the name and description; 4 stars.gglucass/headroom-labs: a repository presented as a context-optimization layer for LLM applications; 3 stars. Its description is not enough to claim full compatibility with the canonical repository.
The other highest-visibility forks returned by the API essentially kept the original’s description; for rigor they are classified as forks rather than independent ports. headroom-zh’s presence does explicitly identify a non-English adaptation.
Repo numbers
Measurement: August 3, 2026, GitHub API and page.
| Metric | Value |
|---|---|
| Stars | 64,238 |
| Forks | 4,883 |
| Subscribers | 192 |
| Commits | 2,408 |
| Open issues reported by the API | 617 |
| Primary language | Python |
| License | Apache-2.0 |
| Created | January 7, 2026 |
| Last metadata update | August 3, 2026 |
| Latest release recovered | v0.33.0, July 29, 2026 |
The top contributors returned by the API were chopratejas (1,089), JerrettDavis (330), abhay-codes07 (90), gglucass (90), and rodboev (85). The 2,408 count comes from GitHub’s history page. The general response’s watchers_count duplicates the star count, so subscribers_count is reported here as the real subscriber figure. The open_issues_count field can include open pull requests; it should not be read as an issue-only count.
How to contribute
The README documents a minimal contribution starting point: clone the repository, run uv sync --extra dev, and launch uv run pytest; it defers the details to CONTRIBUTING.md. It also declares development environments under .devcontainer/, including one for memory work with Qdrant and Neo4j.
The repository contains test, evaluation, and end-to-end test directories, and the README offers to reproduce its suite with python -m headroom.evals suite --tier 1. This allows checking behavior against the project’s own scenarios, but it does not turn its results into an independent evaluation.
How the community received it
The external evidence recovered is limited and mixed, so it does not support inferring broad consensus.
- On Hacker News 48588755, a thread about skepticism toward RTK reached 121 points and 26 comments. User jvican described Headroom as a more legitimate alternative and valued that the repository publishes accuracy tests and explains its algorithms. That is an individual opinion, not a comparison reproduced in this investigation.
- In the launch thread 48999841, submitted by andsoitis, Headroom reached 10 points and 2 comments in the search index; the root item recovered contained one top-level reply. cityofdelusion questioned whether the advertised savings would carry over to real-world agentic coding, asked for a more scientific approach, and asked why providers don’t apply a no-downside improvement by default. It is a concrete objection about methodology and marketing, not an experimental refutation.
- Thread 46602761, posted by chopratejas, registered 2 points and 2 comments at the time it was recovered. It documents the author’s technical explanation and stated limitations, but its size does not evidence broad positive or negative reception.
GitHub activity also shows demand for integrations and operational issues: issue #962, opened by yizems, about the VS Code Copilot plugin, had 102 comments; proposal #74, started by chopratejas, asked for an OpenCode wrapper and had 50. That is evidence of implementation discussion, not a quality assessment.
Headroom versus other approaches
| Approach | Verifiable overlap | Verifiable difference |
|---|---|---|
| Compresr and Token Co. | The README groups them as alternatives that reduce content sent to the model. | The README describes them as calls to a hosted API, while Headroom presents itself as a local tool. |
| OpenAI’s compaction | Both reduce part of a conversation’s context. | The README limits OpenAI’s compaction to conversation history and characterizes it as native to the provider; Headroom claims to cover tools, RAG, logs, files, and history via proxy, library, middleware, or MCP. |
| RTK | Both come up in a community conversation about token savings. | jvican’s favorable comparison on Hacker News is a personal opinion; no shared methodology was recovered that would support claiming Headroom’s superiority over RTK. |
The most relevant practical difference is recoverability: Headroom tries to let the model request the original via CCR. That advantage is only useful when the client can use that path and when the reduced content retains enough signal; it does not eliminate the risk the documentation itself acknowledges for results that require exhaustiveness.
Use cases and who this repository can help
- People running coding agents with large tool outputs can use
headroom wrapor the proxy to shrink search results, logs, and listings before they reach Claude Code, Codex, Copilot CLI, or other compatible clients, without changing application logic in proxy mode. - Teams building assistants around JSON, RAG, or response-heavy APIs can integrate the Python or TypeScript library and use content-based routing to apply different treatments to JSON arrays, code, and prose. If the model needs detail that was lost, CCR offers on-demand local retrieval.
- Teams working across several agents or providers can use the shared memory the project declares and the MCP server so Claude, Codex, Gemini, and Grok access the same compression and retrieval layer. Privacy, retention, and cases that demand every log record should be evaluated first.
- Maintainers who want to measure spend and tune instructions can combine
headroom perf, the dashboard, andheadroom learn --verbosity; Tokview adds a local per-call usage view. The documentation recommends a control group for output savings, so this use case requires validating results against one’s own workload.
Resources
- Canonical repository: https://github.com/headroomlabs-ai/headroom
- Historical repository path: https://github.com/chopratejas/headroom
- Documentation and installation: https://docs.headroomlabs.ai/docs
- Architecture and proof: https://github.com/headroomlabs-ai/headroom#proof
- Python package: https://pypi.org/project/headroom-ai/
- Compression model: https://huggingface.co/headroomlabs-ai/Kompress-v2-base
- Related official repositories: https://github.com/headroomlabs-ai/tokview, https://github.com/headroomlabs-ai/strands-headroom
- Community/Discord: the README links to Discord, but the recovered text does not expose a verifiable server identifier.
- Discussions and reviews: https://news.ycombinator.com/item?id=48588755, https://news.ycombinator.com/item?id=48999841, https://news.ycombinator.com/item?id=46602761
Note: this article combines the Headroom README and page, the GitHub API, and Hacker News conversations recovered on August 3, 2026. Figures change over time; the project’s savings and accuracy claims do not substitute for an independent evaluation.
Comments